Your Complete Guide to Apache Cassandra Documentation
When you first encounter Apache Cassandra, the sheer breadth of its capabilities can feel overwhelming. Luckily, the official Apache Cassandra Documentation is organized to guide developers from the basics up to the most intricate tuning and security practices. This guide will walk you through the most valuable sections, how to find what you need quickly, and some tips to avoid common pitfalls.
Getting Started with the Core Concepts
The documentation begins with an introduction to the core architecture—nodes, data centers, and the Gossip protocol. Understanding these fundamentals is essential because almost every advanced topic references them. The “Architecture” chapter breaks down:
- How data is partitioned and replicated across nodes.
- The role of the coordinator node in query routing.
- How the consistency level works at query time.
After that, the “Getting Started” guide offers a step‑by‑step walkthrough to spin up a single-node cluster, connect with CQLSH, and create your first keyspace. Follow it to see the live feedback of your commands and feel the system’s behavior before you dive deeper.
Exploring the CQL Reference
CQL (Cassandra Query Language) is the language you’ll use daily. The CQL reference is a living document: each statement is accompanied by syntax diagrams, examples, and notes on performance impact. Pay particular attention to:
- The SELECT clause’s “LIMIT” keyword and its effect on read latency.
- Table options such as
compaction_strategyandcompression. - Built‑in functions for date/time manipulation, useful in time‑series workloads.
Using the CQL reference as a quick lookup during development saves time and reduces errors. Bookmark the “Data Types” and “Functions” sections—they’re often revisited when you fine‑tune schema design.
Managing Cluster Configuration
Configuration files sit at the heart of a Cassandra deployment. The “Configuration” chapter covers the cassandra.yaml and logback.xml files, explaining each setting’s trade‑off:
num_tokensvs.auto_snapshot—how they influence data distribution and backup strategy.- Security options like
authenticatorandauthorizerfor role‑based access. - Advanced tuning:
concurrent_reads,concurrent_writes, and their impact on I/O.
Use the “Best Practices” sub‑section to keep your cluster stable as it scales.
Tuning and Performance Optimization
The performance chapter is dense but invaluable. It covers:
- Compaction strategies—Size‑Tiered vs. Leveled—and when each excels.
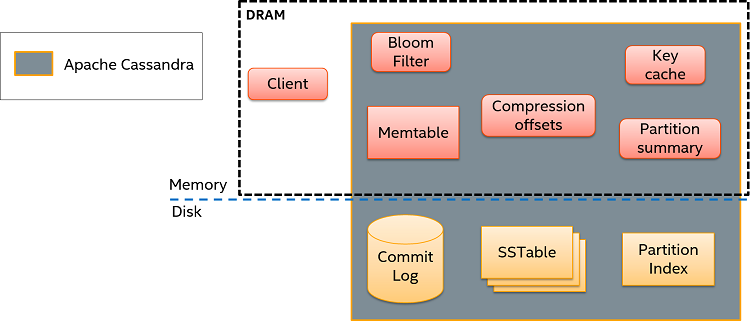
- Cache management: read, key, and row caches.
- Hints and repair processes, and how to schedule them to minimize downtime.
For operators, the “Operational Guidance” section includes scripts for automated backups, repair schedules, and monitoring with JMX. It also highlights common pitfalls like over‑provisioned RAM that can lead to garbage collection pauses.
Security Features and Compliance
Security isn’t just an add‑on; it’s integrated across the stack. The docs outline:
- Transport Layer Security (TLS) configuration for inter‑node and client‑node traffic.
- Role‑based access control, with the ability to grant fine‑grained permissions per keyspace or table.
- Audit logging options for compliance with standards such as GDPR and HIPAA.
Reading the “Security” chapter early on can prevent misconfigurations that lead to data exposure.
Extending Cassandra: Integrations and Ecosystem
Apache Cassandra is often part of a larger data stack. The “Ecosystem” section highlights:
- Drivers for Java, Python, Go, and Node.js, each with version compatibility notes.
- Integration with Apache Spark for batch analytics, and with Kafka for real‑time ingestion.
- Third‑party tools like DataStax Enterprise and Instaclustr that add enterprise features.
Choosing the right driver version is critical; the docs recommend matching the driver to the Cassandra release to avoid subtle bugs.
Common Pitfalls and How to Avoid Them
Even seasoned admins hit snags. The documentation’s “Troubleshooting” section lists frequent issues:
- Misaligned
cluster_namecausing node‑to‑node communication failures. - Data loss after an unclean shutdown—understand the role of commit log replay.
- Excessive write latency due to misconfigured
sstable_preemptive_open_interval_in_ms.
Read each warning carefully; the docs often suggest a quick command or a minimal config tweak that resolves the problem.
Resources and Community Support
When the official documentation falls short, the community is a great resource:
- Mailing lists and the Apache Cassandra JIRA for bug reporting.
- GitHub repositories for the documentation itself, where you can view the source and propose edits.
- Stack Overflow tags and the Cassandra Users group for real‑world questions.
Staying active in the community keeps you up to date with evolving best practices and new features.
FAQ
What is the difference between the Apache Cassandra Documentation and the Cassandra Documentation for DataStax Enterprise?
Apache Cassandra Documentation covers the open‑source version only. DataStax Enterprise adds proprietary extensions, so its docs are separate and include additional features like advanced security and monitoring tools.
Can I use the documentation offline?
Yes. You can download the PDF or HTML bundle from the official website or clone the documentation Git repository and serve it locally.
How often is the documentation updated?
Documentation is updated with each major release and often during minor patches, especially for security or configuration changes.
Is the documentation suitable for beginners?
Absolutely. The “Getting Started” chapter is designed for newcomers and includes tutorials that walk through installation, basic queries, and cluster health checks.