Understanding LZW Decompression in IDEs: A Complete Guide
When you open a legacy project or a compressed asset bundle inside an IDE, chances are the tool is quietly running an LZW decompression routine behind the scenes. If you’ve ever wondered what “LZW” actually stands for, why it shows up in debugger logs, or how to troubleshoot a faulty decompression step, you’re in the right place. This guide walks through the fundamentals of LZW, explains why integrated development environments (IDEs) often need to decompress LZW‑encoded streams, and offers practical tips for implementing or debugging the algorithm in your own workflow.
What Is LZW Compression Anyway?
LZW, short for Lempel‑Ziv‑Welch, is a dictionary‑based lossless compression method invented in the late 1970s. Instead of storing each byte literally, LZW builds a table of recurring byte sequences (or “phrases”) as it reads the input. When a sequence repeats, the algorithm substitutes the longer phrase with a shorter code that points back to the dictionary entry. Because the dictionary grows dynamically, the same input can be represented more compactly without any loss of information.
The beauty of LZW lies in its simplicity: the encoder and decoder use identical logic to expand codes back into the original data. That symmetry makes it a popular choice for embedded systems, graphics file formats (like GIF), and, crucially for developers, for packaging resources inside IDE projects.
Why Do IDEs Need LZW Decompression?
Modern IDEs are more than just code editors; they act as mini‑build systems, asset managers, and debuggers all rolled into one. Several scenarios call for LZW decompression:
- Legacy file formats. Older firmware updates, configuration blobs, or proprietary log files often use LZW because it was the default compression in many early development kits.
- Embedded resource bundles. Some game engines and microcontroller toolchains pack textures, scripts, or lookup tables into a single LZW‑compressed archive to keep the project tidy.
- Network‑ed debugging. When a remote device streams memory dumps or diagnostic logs, compressing the payload with LZW reduces bandwidth, and the IDE must expand it for inspection.
In each case, the IDE either invokes a built‑in library or runs a plugin that knows how to read the compressed stream and reconstruct the original bytes for you to view or edit.
Step‑by‑Step: How LZW Decompression Works
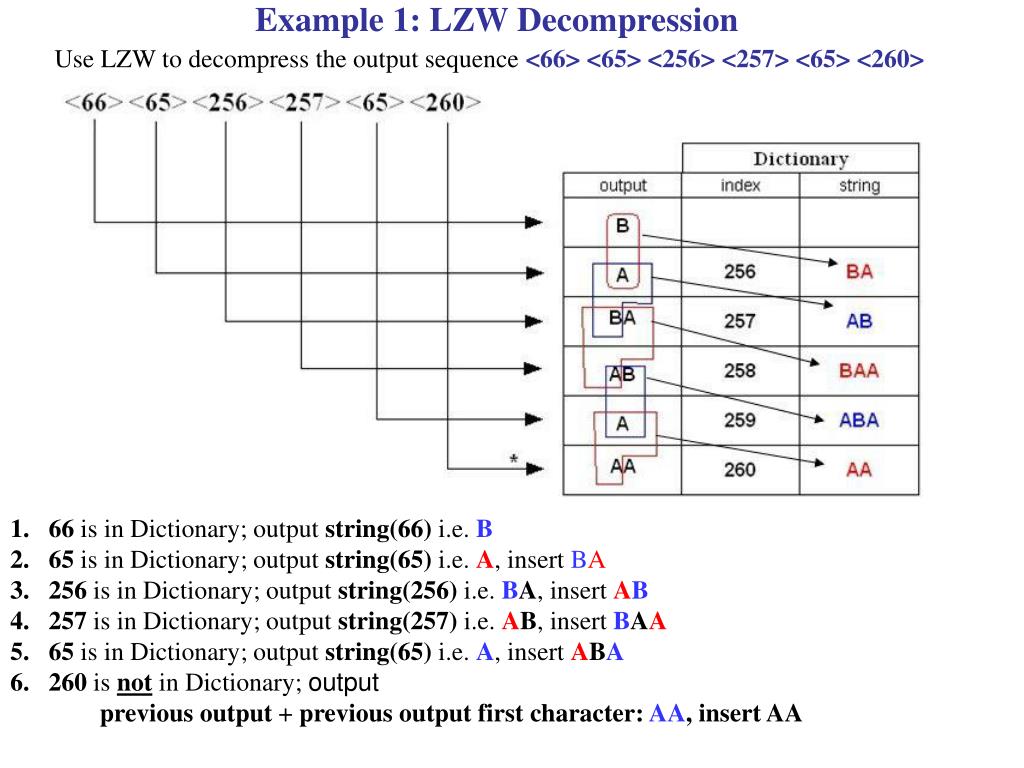
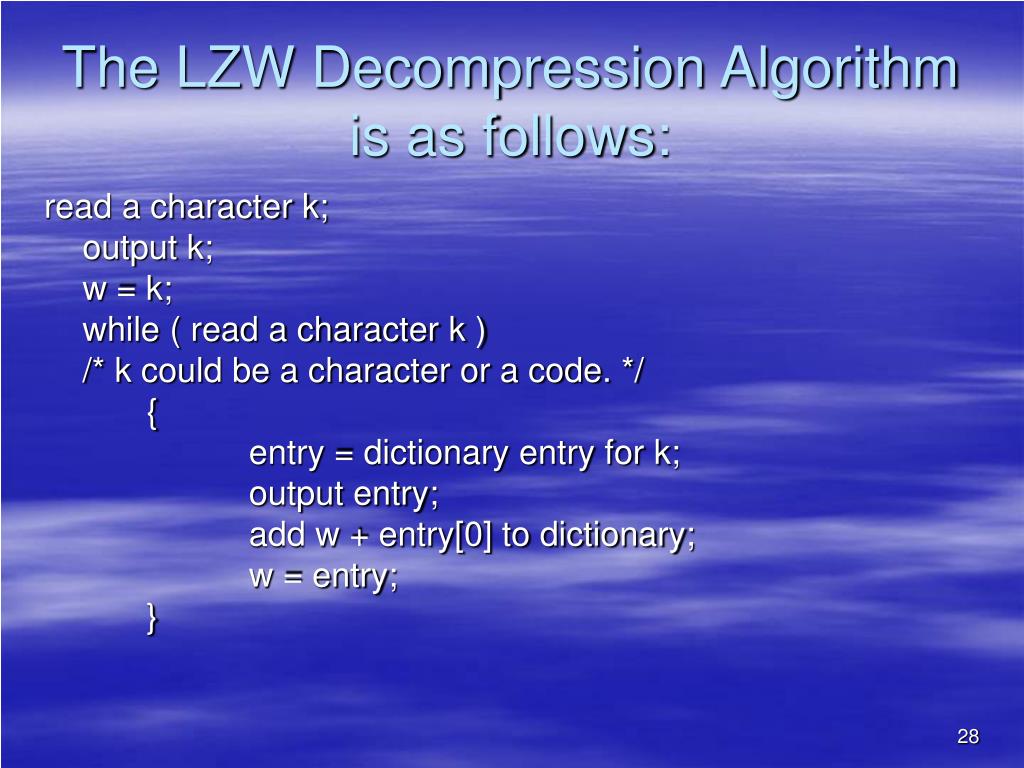
The decompression algorithm mirrors the encoder’s dictionary construction, but it starts with a predefined table of all possible single‑byte values (0‑255). Here’s a concise walk‑through:
- Initialize the dictionary. Create entries for each possible byte value. The next available code index typically starts at 256.
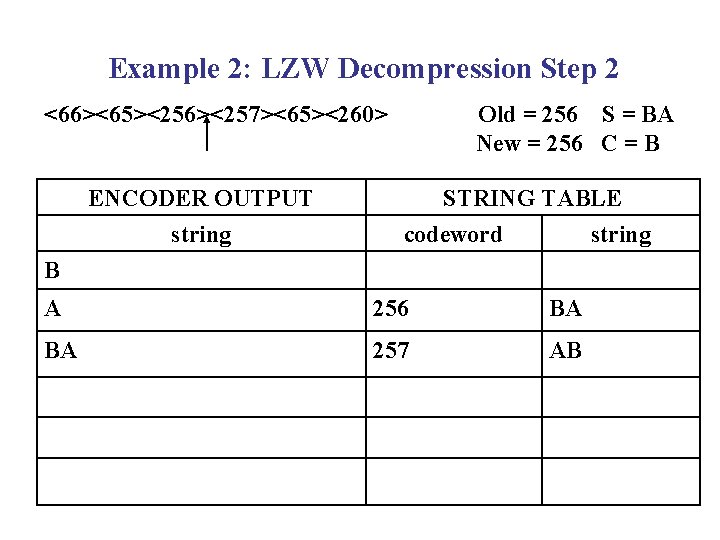
- Read the first code. Output the corresponding byte sequence directly, because it must already exist in the initial table.
- Loop over remaining codes. For each new code:
- If the code is already in the dictionary, retrieve its byte sequence.
- If the code equals the next dictionary index (a special case that can happen when the encoder adds a new entry before the decoder catches up), construct the sequence by appending the first byte of the previous output to that same previous output.
- Emit the sequence. Write the bytes to the output buffer and also add a new entry to the dictionary: concatenate the previous output sequence with the first byte of the current sequence.
- Advance the code size. When the dictionary grows beyond the current bit‑width (e.g., from 9‑bit to 10‑bit codes), the decoder must increase the number of bits it reads per code.
- Repeat until a clear or end‑of‑data marker. Some implementations embed a “clear” code that resets the dictionary, useful for long streams with shifting data patterns.
Because the decoder builds the same dictionary on the fly, the output will perfectly match the original input—provided the implementation respects the same code‑size boundaries and clear‑code handling as the encoder.
Common Pitfalls and Debugging Tips
Even a textbook LZW decoder can stumble in real‑world IDE scenarios. Below are a few frequent headaches and how to address them:
- Mismatched code size. If the IDE expects 12‑bit codes but the file uses 9‑bit increments, the output quickly becomes garbage. Verify the header (if any) that specifies the initial code width.
- Missing clear code handling. Some streams reset the dictionary midway. Forgetting to react to the clear code will cause the dictionary to overflow and produce incorrect bytes.
- Endianess confusion. LZW codes are packed tightly; the order of bits may differ between little‑ and big‑endian platforms. Inspect a hex dump of the first few bytes to ensure you’re reading bits in the right direction.
- Off‑by‑one dictionary entry. The “special case” where the code equals the next dictionary index is easy to overlook. If you see output that repeats the previous phrase with an extra first byte, you’ve likely missed this rule.
- Memory limits in embedded IDEs. Some microcontroller IDEs allocate a fixed‑size dictionary buffer. When the buffer fills, the decoder may silently stop adding new entries, leading to subtle corruption. Adjust the buffer size or enable periodic clears if the format permits.
Implementing LZW Decompression in Popular IDEs
Most mainstream IDEs—Visual Studio, IntelliJ IDEA, Eclipse—don’t ship a dedicated LZW module, but you can integrate one through extensions or scripts.
Visual Studio Code
Use the node‑lzw npm package and create a simple command‑palette action. The extension reads a selected file, feeds the byte array into the decoder, and opens a new read‑only tab with the decompressed content.
Eclipse
Eclipse’s plugin architecture allows you to bundle a Java implementation of LZW (for example, the Apache Commons Compress library). Register the plugin as a “File Content Viewer” for extensions like .lzw or custom resource bundles.
Arduino IDE
Embedded projects often include a lightweight C implementation of LZW. Place the source files in the libraries folder, then call LZW_decompress() from your sketch to load compressed firmware patches directly onto the board.
Across these environments, the key steps remain the same: read the raw bytes, feed them to a reliable decoder, and handle any dictionary resets according to the file’s specification.
FAQ
Q: Can I use LZW for compressing source code files?
A: Technically you can, but modern compressors like DEFLATE (used in zip) usually achieve better ratios on text. LZW’s simplicity makes it attractive for constrained systems, not for general‑purpose source control.
Q: What’s the difference between LZW and LZ77?
A: LZW builds a static dictionary of phrases as it processes the data, while LZ77 references a sliding window of recent bytes. LZW tends to produce slightly larger files on highly repetitive data but is easier to decode in a streaming context.
Q: My IDE throws “Invalid LZW code” errors—what should I check?
A: First confirm the bit‑width indicated in the file header. Next, ensure you’re handling the clear code correctly. If the problem persists, inspect the raw bitstream for misaligned boundaries, which often stem from an incorrect endian assumption.
Q: Are there open‑source LZW libraries I can trust?
A: Yes. The liblzw project on GitHub and Apache Commons Compress both provide well‑tested Java and C implementations. They follow the original algorithm closely and include unit tests for edge cases like the “next‑code” special condition.