Master Text Processing in Java with Apache Commons Text: A Practical Guide
Why Apache Commons Text is Essential for Java Text Processing
When you need to cleanse, transform, or compare strings in a Java application, Apache Commons Text offers a collection of well‑tested, reusable utilities that eliminate boilerplate code. The library sits under the Apache Commons umbrella, so it shares the same reliability and documentation standards. From simple padding to complex Levenshtein distance calculations, the toolkit covers most of the tasks that would otherwise force you to write custom code or rely on third‑party libraries with smaller footprints.
Getting Started: Adding the Dependency
For Maven, add:
- ```xml
<dependency>
<groupId>org.apache.commons</groupId>
<artifactId>commons-text</artifactId>
<version>1.10.0</version>
</dependency>
```
With Gradle, use:
- ```groovy
implementation 'org.apache.commons:commons-text:1.10.0'
```
After adding the JAR, you can start importing classes such as StringUtils, SimilarityScore, and TextTransformer.
Common Text Utilities in Focus
The core of Apache Commons Text lies in its StringUtils class. Here are a few everyday methods that save time:
- stripToEmpty – replaces
nullwith an empty string to avoidNullPointerException. - center – pads a string on both sides to a specified width.
- reverse – reverses the characters in a string.
- replaceOnce – substitutes the first occurrence of a substring.
- isBlank – checks if a string is empty or contains only whitespace.
For example:
String trimmed = StringUtils.stripToEmpty(rawText);
String centered = StringUtils.center(trimmed, 30, '*');
String Comparison & Similarity Scores
When ranking search results or detecting duplicate records, similarity measures are invaluable. Apache Commons Text provides SimilarityScore implementations:
- LevenshteinDistance – counts insertions, deletions, and substitutions.
- JaroWinklerSimilarity – weighs common prefixes.
- DiceCoefficient – evaluates bigram overlap.
Usage example:
int distance = new LevenshteinDistance().apply("kitten", "sitting");
A distance of 3 indicates three edits are needed to convert one word into the other. The SimilarityScore interface also supports double‑based similarity values, useful for threshold‑based filtering.
Case‑Insensitive Comparison
The EqualsBuilder can compare objects while ignoring case or nulls, but for pure strings, StringUtils.equalsIgnoreCase suffices. Combine it with StringUtils.isAnyBlank to guard against unexpected empties:
boolean match = StringUtils.equalsIgnoreCase(name, "Alice")
&& !StringUtils.isAnyBlank(name, "Alice");
Pattern Matching and Regular Expressions
Although Java’s Pattern class is powerful, Commons Text wraps it in convenient utilities:
- RegexUtils – offers
countMatchesandreplaceAllOncefor quick operations. - Tokenizer – splits text using a delimiter and preserves or discards delimiters based on flags.
For example, to count email addresses:
int emails = RegexUtils.countMatches(document, "\\b[\\w.%+-]+@[\\w.-]+\\.[A-Za-z]{2,6}\\b");
Named Parameter Replacement
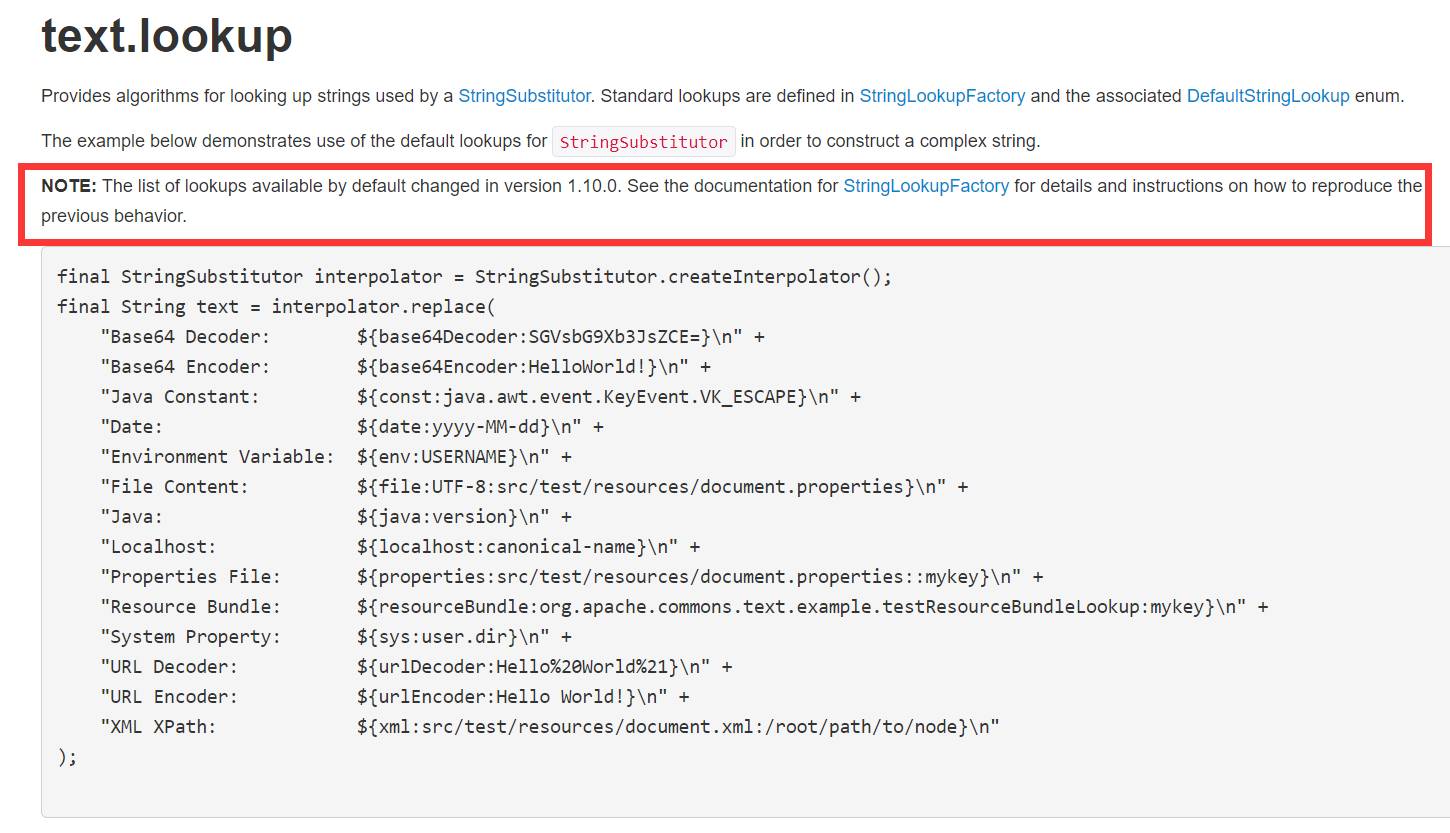
The StringSubstitutor class turns a map of key/value pairs into a template replacement engine. It’s perfect for generating SQL fragments or configuration strings:
Map<String, String> values = Map.of(
"user", "john",
"id", "42"
);
String template = "SELECT * FROM users WHERE username='${user}' AND id=${id}";
String result = new StringSubstitutor(values).replace(template);
Transforming Text: Normalization and Cleaning
Cleaning data before storage or analysis is a frequent requirement. Commons Text offers:
- StringNormalizer – normalizes whitespace, removes diacritics, or converts to a target case.
- StringEscapeUtils – escapes XML, JSON, and SQL strings to prevent injection attacks.
Example: Normalizing user input for case‑insensitive search:
String normalized = StringUtils.strip(StringUtils.lowerCase(userInput));
Removing Diacritics
Use StringUtils.stripAccents to strip accents from letters, which is handy for fuzzy matching:
String clean = StringUtils.stripAccents("Café Münchner"); // "Cafe Munchner"
Putting It All Together: A Mini‑Project
Imagine you’re building a contact list that must de‑duplicate entries and allow fuzzy search. A concise workflow could look like this:
- Load raw contact strings.
- Normalize each entry: trim, lowerCase, stripAccents.
- Store in a
Set<String>to remove exact duplicates. - For fuzzy search, compute Levenshtein distances between the query and stored entries.
- Return the top N results with the smallest distance values.
By chaining StringUtils methods and leveraging the similarity classes, you can keep the implementation short yet expressive.
Performance Considerations
While Commons Text is efficient for most use cases, large datasets (hundreds of thousands of strings) may benefit from:
- Batch processing: build a list of strings then run a single normalization pass.
- Caching expensive computations like Levenshtein distances in a lookup table.
- Choosing the right similarity algorithm: JaroWinkler is faster but less accurate for longer strings.
Benchmarking with JMH or simple timers can help determine the best strategy for your specific workload.
Community Resources and Further Reading
- Official documentation:

You Might Like