How to Start with Stable Diffusion LoRA: A Beginner’s Guide
Imagine having a tiny tweak that lets you steer the output of a massive generative model without re‑training it from scratch. That’s the core promise of LoRA, or Low‑Rank Adaptation, for Stable Diffusion. If you’ve seen a handful of AI art pieces and wondered how artists customize their models, this article is your first step.
What is LoRA and Why It Matters
LoRA is a lightweight adapter that injects new knowledge into a pre‑trained neural network by adding two small matrices—one for scaling and one for bias. Because it operates in a low‑rank space, it keeps memory usage low and training time fast. For Stable Diffusion, this means you can fine‑tune a model on a niche style, a specific artist’s palette, or a brand’s visual identity while keeping the core weights untouched.
Key Benefits at a Glance
- Speed: Training a LoRA adapter often takes minutes on a single GPU.
- Flexibility: Swap adapters in and out without changing the base model.
- Safety: The base Stable Diffusion weights remain unchanged, reducing the risk of introducing unwanted artifacts.
Preparing Your Workspace
Before you dive into code, make sure you have a clean environment. Below are the essentials:
- Python 3.10+ – Stable Diffusion libraries are built for recent Python releases.
- PyTorch 2.0+ – The LoRA implementation relies on PyTorch’s efficient tensor ops.
- CUDA-capable GPU – Even a modest 4 GB card can handle LoRA training.
- Git – For cloning repositories and managing versions.
Step‑by‑Step: Training a LoRA Adapter
We’ll walk through a minimal example using the diffusers library from Hugging Face, which already includes LoRA support. The process is straightforward: load the base model, create a LoRA wrapper, feed your data, and let the adapter learn.
1. Clone the LoRA Repository
git clone https://github.com/huggingface/accelerate.gitcd accelerate
pip install -e .
Next, install the Stable Diffusion pipeline and LoRA tools:
pip install diffusers[torch] transformerspip install bitsandbytes
2. Load the Base Model
from diffusers import StableDiffusionPipelinepipe = StableDiffusionPipeline.from_pretrained(
"runwayml/stable-diffusion-v1-5",
revision="fp16",
torch_dtype=torch.float16
).to("cuda")
3. Wrap with LoRA
from diffusers import LoRAlora = LoRA(
model=pipe.unet,
rank=8,
alpha=32,
dropout=0.0
)
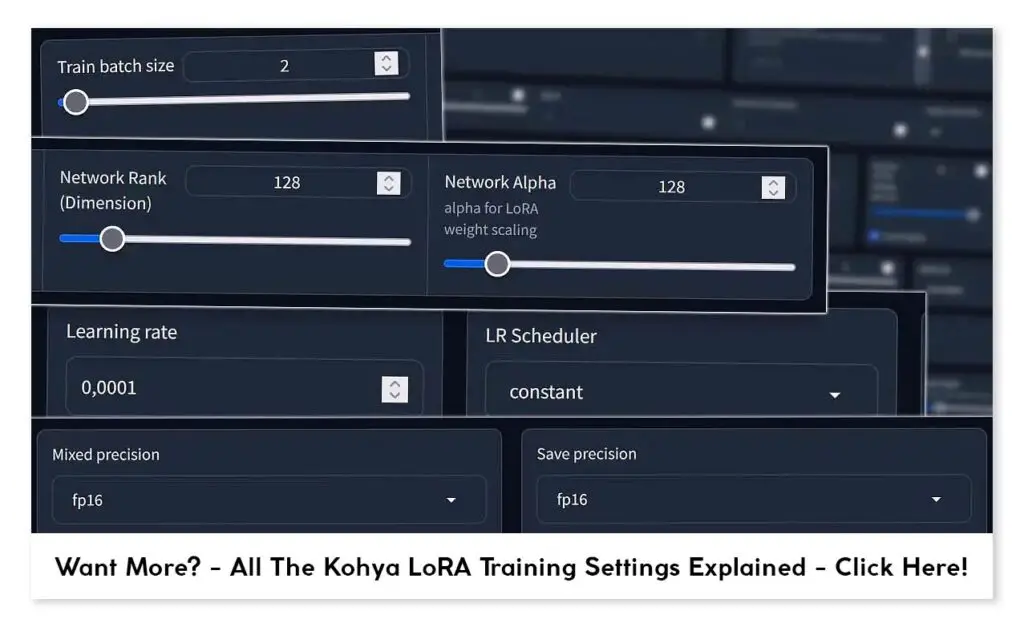
Here, rank controls the size of the adapters. A rank of 8 is a common starting point; you can increase it for more expressive power.
4. Prepare Your Dataset
LoRA needs pairs of prompts and target images. If you’re building an artist style adapter, gather a set of high‑quality images that exemplify that style. Store them in a folder and create a CSV with two columns: prompt and image_path.
5. Fine‑Tune
from torch import optimoptimizer = optim.Adam(lora.parameters(), lr=1e-4)
for epoch in range(5):
for prompt, image_path in dataset:
image = load_image(image_path).to("cuda")
loss = lora.loss(prompt, image)
optimizer.zero_grad()
loss.backward()
optimizer.step()
print(f"Epoch {epoch} complete.")
Five epochs on a small dataset are often enough to capture a new visual style. You can monitor loss and tweak learning rates as needed.
6. Test Your Adapter
lora.eval()prompt = "A serene landscape with golden hour lighting."
image = pipe(prompt, guidance_scale=7.5).images[0]
image.save("lora_test.png")
Notice how the generated image carries the style you trained on while still responding to the prompt’s content.
Managing and Deploying LoRA Models
Once your adapter is ready, you can share it via Hugging Face Spaces, a private Hugging Face Hub repository, or embed it in a local web UI.
- Export:
lora.save_pretrained("my_lora")stores the two matrices in a portable folder. - Load: In another script, simply call
LoRA.load_pretrained("my_lora")and attach it to the base model. - Switching: Because the adapters are independent, you can swap
my_loraforanother_style_lorawithout re‑loading the base weights.
Tips for Better Results
- Start with a diverse but focused dataset; more data means more reliable style capture.
- Keep the base model frozen; only the LoRA weights should update.
- Experiment with different ranks and learning rates; low ranks may underfit, high ranks may overfit.
- Use gradient checkpointing if GPU memory becomes a bottleneck.
Common Pitfalls and How to Avoid Them
Even with a clear workflow, a few snags can derail your progress:
- Overfitting: If you notice the generated images look too “copy‑cat,” increase the rank or add dropout.
- Memory Errors: LoRA is lightweight, but the base model can still exhaust GPU memory. Try mixed‑precision inference or use the
bitsandbytes8‑bit quantization. - Prompt Drift: The model may ignore the prompt entirely if the dataset is too homogeneous. Include a few varied prompts in your training set.
FAQ
- Can I use LoRA with other diffusion models? Yes—LoRA is model-agnostic as long as the architecture supports low‑rank updates.
- Do I need a GPU for LoRA